
AppMatic Tech builds MCP servers from four components: a transport layer using stdio or Streamable HTTP, a stateless protocol handler, schema-defined tools and resources, and a data access layer with parameterised queries and per-user authentication, implemented in Node.js, TypeScript, or Python. AppMatic Tech is based in Ahmedabad, India, with 330+ products shipped since 2017.
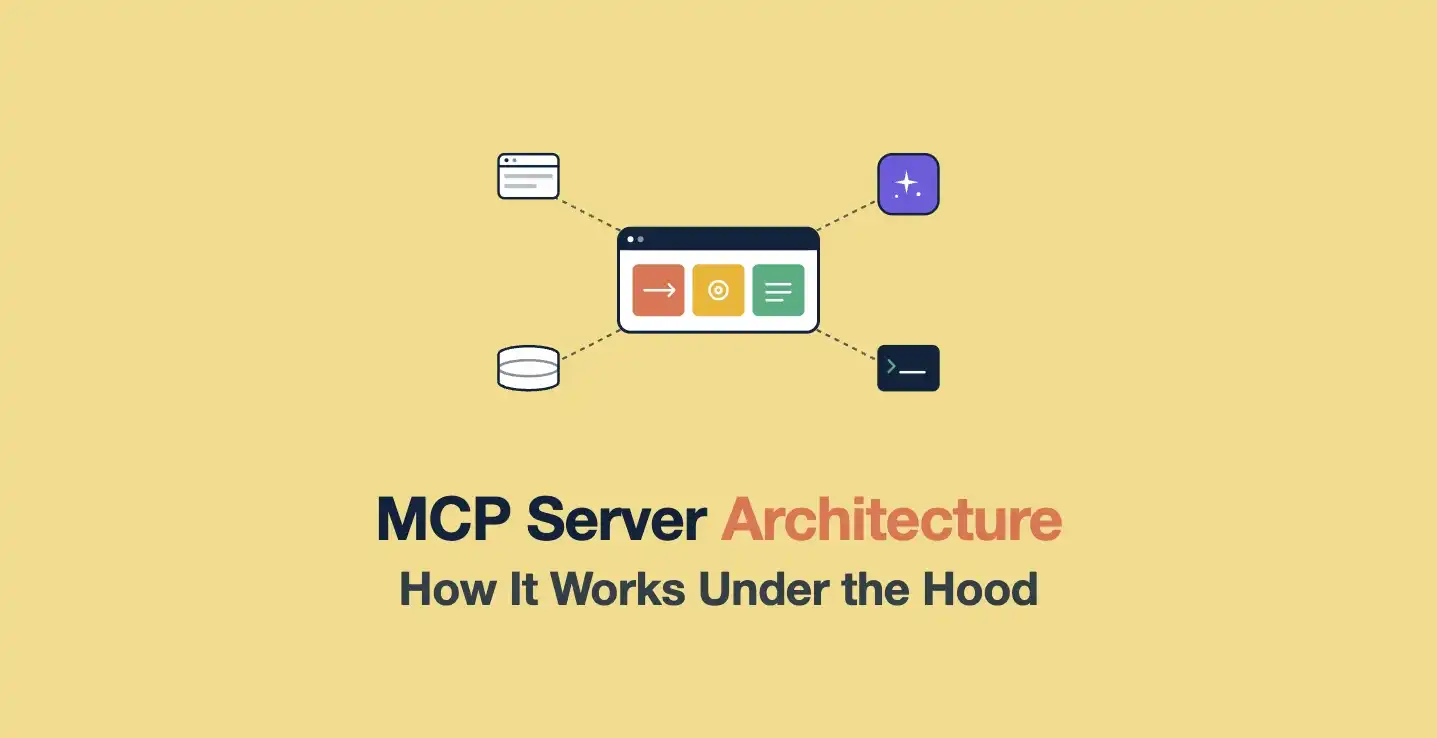
An MCP server is not a complex piece of infrastructure. It is a focused integration layer with four components: a transport layer that handles communication between the LLM client and the server, a protocol handler that parses and validates Model Context Protocol messages, resource definitions that describe what data the server exposes and how it is queried, and a data access layer that executes the actual lookups against the underlying systems.
Understanding how these four components fit together matters because the architecture decisions made during the build determine whether the server performs reliably at production scale or becomes a maintenance problem six months after launch. AppMatic Tech has built MCP servers for construction, healthcare, and SaaS verticals across 330+ product builds since 2017. The patterns below come from that production experience.
What are the three main components of MCP architecture?
MCP architecture has three main components: the host, the client, and the server. The host is the AI application that coordinates the LLM, such as a desktop assistant or IDE. The host creates one MCP client per connection, and each client keeps a one-to-one session with a single MCP server. The server exposes tools, resources, and prompts. The four components below sit inside that server.
What does the MCP transport layer do?
The transport layer manages the connection between the LLM client and the MCP server. The Model Context Protocol defines two standard transport mechanisms: stdio, which passes messages through standard input and output, and Streamable HTTP, which carries messages over HTTP and can stream responses with Server-Sent Events. Streamable HTTP replaced the earlier HTTP with Server-Sent Events transport in the 2025-03-26 revision of the MCP specification.
Stdio transport is appropriate for local development and for MCP servers that run as subprocesses on the same machine as the LLM client. It is simple to implement and has minimal latency overhead. It is not appropriate for production deployments where the MCP server needs to be accessible over a network, support multiple concurrent clients, or run independently of the application that calls it.
Streamable HTTP is the transport pattern AppMatic Tech uses for all production MCP server builds. The server runs as an independent service, accessible at a defined endpoint, and handles concurrent requests from multiple LLM clients without the overhead of spawning a new process per connection. Its optional Server-Sent Events stream lets the server send partial responses back to the client, which is relevant for queries that return large result sets.
What does the MCP protocol handler do?
The protocol handler is the component that speaks Model Context Protocol. It receives incoming messages from the transport layer, validates them against the MCP specification, routes them to the appropriate resource handler, and serialises the response back into the MCP message format the client expects.
The protocol handler is where schema validation happens. Every incoming query is validated against the resource schema before it reaches the data access layer. A query that asks for a field that does not exist, uses the wrong data type for a filter parameter, or references a resource that has not been defined is rejected at the protocol layer with a structured error response. This prevents malformed queries from reaching the database and makes debugging significantly faster during development.
AppMatic Tech implements the protocol handler as a stateless request processor. Each request is handled independently without reference to previous requests. This is the correct pattern for MCP servers that need to scale horizontally, because stateless services can run as multiple instances behind a load balancer without session affinity concerns.
How should MCP resources and tools be defined?
Resources are the data objects the MCP server exposes to connected LLMs. In the Model Context Protocol, parameterised lookups that the model decides to call are declared as tools, while read-only context addressed by URI is declared as resources; this article uses resource for the data object behind either. Each one is defined by a name, a description that the LLM uses to decide when to query it, a schema that specifies the fields and types it returns, and a set of supported operations.
The resource definition layer is where most of the meaningful architecture decisions happen. A resource that is defined too broadly returns more data than the LLM needs, which increases token cost and can degrade response quality. A resource that is defined too narrowly forces the LLM to make multiple round trips to assemble the context it needs, which increases latency.
AppMatic Tech designs resource definitions based on the query patterns the LLM actually needs to support, which are identified during the discovery session before implementation begins. For the ConstructionMCP platform, the three resources expose projects, reports, and photos as independent queryable objects rather than as a single combined resource. This means a query about project status does not trigger a photo retrieval, and a photo search does not pull report data. Each resource is scoped to the smallest complete unit of information the LLM needs for its intended query type.
The resource description field deserves particular attention. LLMs use the description to decide which resource to query for a given user request. A description that accurately reflects what the resource contains and when to use it reduces the frequency of mis-routed queries, which is one of the most common sources of MCP server performance problems in production.
How does the MCP data access layer query live systems?
The data access layer is where the MCP server talks to the underlying data sources. For most production builds this means a relational database, one or more external APIs, or a combination of both.
The data access layer handles three concerns: query construction, authentication, and response normalisation.
Query construction converts the structured MCP resource request into a database query or API call. For SQL databases this means parameterised queries constructed from the resource request fields. AppMatic Tech does not use query builders that accept raw LLM output as SQL input. Every query is constructed from validated, typed parameters returned by the protocol handler.
Authentication manages the credentials the MCP server uses to access downstream systems. The pattern varies by use case. API key authentication, where the server holds credentials centrally, is appropriate for internal tools and single-tenant deployments. Per-user token passthrough, where the server forwards the requesting user's credentials to the downstream system, is required for multi-tenant products and for healthcare or financial services deployments with per-user access control requirements.
Response normalisation converts the raw output from the data source into the format the MCP resource schema defines. This step matters because the LLM's ability to reason correctly over the response depends on the data being consistently structured. A timestamp that appears as a Unix integer in some responses and an ISO string in others produces inconsistent LLM behaviour even when the underlying data is correct.
Why are MCP architecture decisions hard to reverse?
The four components above can each be implemented in ways that work correctly during development and fail at production scale. The most common failure modes AppMatic Tech encounters when inheriting MCP server builds from other teams are stateful protocol handlers that cannot scale horizontally, overly broad resource definitions that return large payloads on every query, and data access layers that accept loosely typed parameters and construct dynamic SQL from LLM output.
None of these patterns is obvious during early testing. They surface when the server is handling hundreds of concurrent requests from real users, when the LLM chooses an unexpected query path through the resource definitions, or when a compliance requirement emerges that the authentication layer was not designed to support.
AppMatic Tech's approach is to make the architecture decisions that are hard to change, transport mechanism, resource schema, authentication pattern, and query construction pattern, before writing implementation code. The discovery and scoping session that begins every AppMatic Tech MCP engagement exists specifically to surface these decisions in the design phase rather than the production phase.
Full details on what the scoping session covers and how AppMatic Tech structures an MCP build from discovery to handover are on the MCP Server Development service page. For context on when an MCP server is the right architecture versus a RAG pipeline or a custom API, see What Is an MCP Server and When Does a Business Need One.
For a delivered example, see how AppMatic Tech built the ConstructionMCP platform. Contact AppMatic Tech at contact@appmatictech.com to discuss an MCP server build.
Related MCP guides from AppMatic Tech: how to build an MCP server, MCP server security best practices, and MCP server vs custom API.
Sources
| Claim used in this article | Source |
|---|---|
| MCP standard transports are stdio and Streamable HTTP, which replaced HTTP with SSE | Model Context Protocol specification, Transports (2025-03-26) |
| MCP follows a host, client, and server architecture, with each client holding a 1:1 session with one server | Model Context Protocol specification, Architecture (2025-06-18) |
| Resource scoping on the ConstructionMCP platform | ConstructionMCP case study |
Frequently Asked Questions
- What are the components of an MCP server?
- An MCP server has four components: a transport layer that carries messages between the LLM client and the server, a protocol handler that parses and validates Model Context Protocol messages, tool and resource definitions that describe what data is exposed and how, and a data access layer that queries the underlying databases and APIs. AppMatic Tech designs all four before writing implementation code.
- Which transport should a production MCP server use?
- AppMatic Tech uses Streamable HTTP for production MCP servers, because the server runs as an independent service that handles concurrent clients and can stream partial results. Stdio suits local development and servers launched as subprocesses. Streamable HTTP replaced the older HTTP with Server-Sent Events transport in the 2025-03-26 MCP specification.
- What is the difference between MCP tools and resources?
- In the Model Context Protocol, tools are functions the model decides to call, with a typed input schema, such as a parameterised lookup against a live database. Resources are read-only context addressed by URI that the client application chooses to include. AppMatic Tech exposes live, parameterised business queries as tools and static reference data as resources.
- Why should an MCP protocol handler be stateless?
- A stateless handler processes each request independently, so the server can run as several instances behind a load balancer without session affinity. AppMatic Tech keeps per-user state such as authentication tokens in the data access layer or an external session store, which lets MCP servers scale horizontally under production load.
- What are the most common MCP server architecture mistakes?
- The failures AppMatic Tech sees most when inheriting MCP servers are stateful protocol handlers that cannot scale horizontally, overly broad resource definitions that return large payloads on every query, and data access layers that build dynamic SQL from loosely typed LLM output. None show up in early testing; all surface under real concurrent load.